Sieve
An adaptive web-scraping engine that tests every site before touching it, picks the lightest method that sees the real content, and hands back clean, de-duplicated text.
290
pages crawled across 4 very different sites in 2:13
4 of 4
sites given the right engine by the probe
220
duplicate pages removed automatically
75%
CPU ceiling held by the resource governor
Inside the product
See it working
Real screens and a recorded run, captured from the working product.
Live run on a real PC: CPU and memory gauges, and the resource governor backing off when memory passes its 80% ceiling.
01 / 27My role
Sole engineer: the probe, the three fetch engines, the resource governor, the cleaning pipeline and the bilingual control room.
The problem
Most scrapers send the same request to every site and leave you to clean up the mess: bot walls return challenge pages, JavaScript apps return empty shells, and what does come back is full of menus, footers, cookie banners and duplicates. Pushing harder on a laptop just pins the CPU at 100%.
What I built
Sieve starts every site with an eight-step probe: a plain request, challenge-page detection (Cloudflare and similar), static HTML compared with a rendered copy, robots.txt, sitemaps and feeds, and the page structure. The result is a plan with an engine, a discovery method, per-host concurrency, delay, scrolling and extraction mode, plus a confidence score and the reasons in plain words.
During the crawl each site starts on the engine the probe chose and escalates by itself when it gets blocked or receives an empty JavaScript shell: HTTP/2 first, then a browser-grade TLS fingerprint ("stealth"), then headless Chromium with scrolling and API capture. Every page then goes through a cleaning pipeline: main-content extraction cross-checked with trafilatura, boilerplate blocks learned across the site and removed from every page, Arabic and Latin normalisation, language detection, quality scoring, exact and near-duplicate removal (SHA-256 and SimHash) and optional PII redaction. PDF, DOCX, PPTX and XLSX links are downloaded and their text extracted, and optional AI fields use Gemini to fill typed values per page from a plain-language description.
Architecture
A Python FastAPI engine with httpx (HTTP/2), curl_cffi (browser TLS fingerprints) and Playwright Chromium, lxml and trafilatura for extraction, and aiosqlite on SQLite with FTS5 for storage and full-text search. A Next.js 16 static control room with React 19, Tailwind CSS 4, Motion, TanStack Query and Zustand is served by the engine and updated live over WebSocket. Jobs can be paused, resumed, re-run, scheduled with incremental runs or started by dropping a file into an inbox folder, and they resume after a crash.
Challenges
Going as fast as the machine allows without ever hitting 100%. A resource governor samples CPU and memory every second and raises or lowers concurrency (AIMD) under Eco, Balanced, Turbo or Custom ceilings, while each host gets its own throttle that backs off on 429, Retry-After and slow responses. Crawl traps such as calendar pages and endless query strings are capped.
Key engineering decisions
Probe first, then use the lightest engine that sees the real content, because a browser for every page is slow and plain HTTP misses half the modern web. Learn boilerplate across a site instead of guessing it per page. Keep every engine choice explainable and overridable by hand.
Results & impact
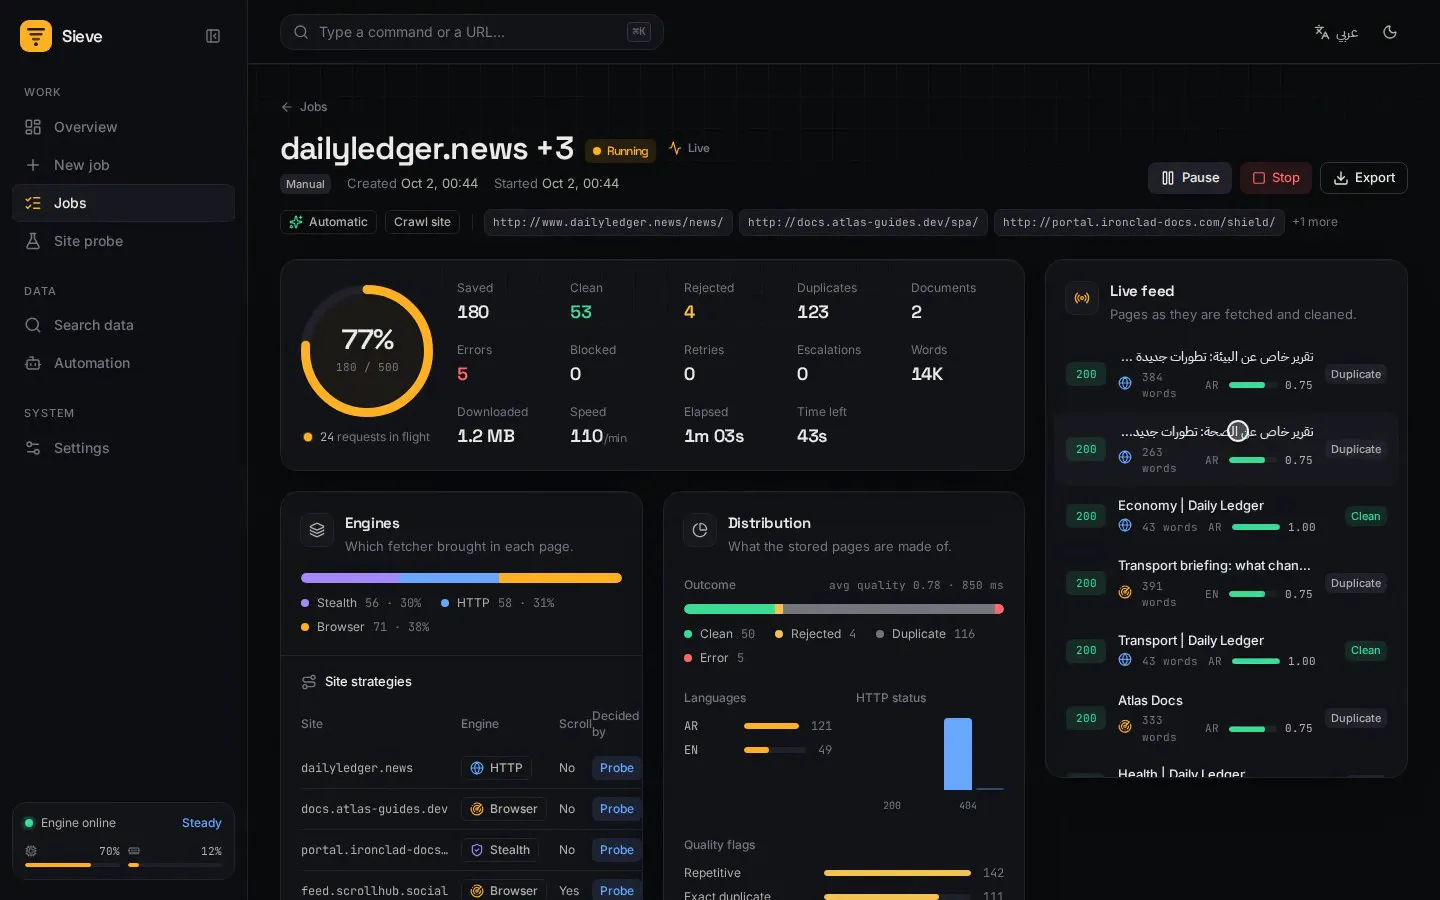
In one recorded job on four very different test sites (a server-rendered Arabic and English news portal, a JavaScript-only documentation app, a knowledge base behind a Cloudflare-style bot wall and an infinite-scroll feed), the probe picked the right engine for every site: HTTP for the portal (36 URLs from its sitemap), Browser for the JavaScript app (9 words in raw HTML against 216 rendered), Stealth for the bot wall (plain HTTP got a 403 challenge, the browser-grade fingerprint passed) and Browser with auto-scroll for the feed. It fetched 290 pages in 2 min 13 s, removed 220 duplicates and 280 repeated template blocks, extracted 4 documents and kept 47 clean, unique pages with an average quality of 0.80, while the governor held the CPU under its 75% ceiling. A second run filled four Gemini AI fields for 6 Arabic and English articles with one call per page.
Highlights
- Any input: pasted links or prose, TXT, CSV, TSV, JSON, XLSX, sitemaps and HTML
- Eight-step site probe with a recommended plan, confidence score and reasons
- Three engines with automatic per-page and per-site escalation, or forced by hand
- Resource governor with live gauges of used, free and reserved memory and four profiles
- Polite crawling: per-host throttling, Retry-After, robots.txt and crawl-trap limits
- Cleaning pipeline with cross-page boilerplate removal, Arabic normalisation, quality scoring and near-duplicate removal
- Structured fields by CSS, XPath or regex, plus Gemini AI fields with a typed schema
- Full-text search and exports to JSONL, JSON, CSV, Excel, Markdown and plain text
- Schedules, inbox folder and crash-safe checkpoints
- English and Arabic control room with RTL, dark and light themes and a command palette
- Tested live on real sites from a Windows PC: Indeed through Cloudflare with the stealth engine, G2's DataDome wall reported honestly, and Hacker News crawled at the 30 s delay its robots.txt asks for